An HTCondor Pool for Lab Research Computing
I operate an HTCondor pool that lets researchers share the lab’s CPU and GPU workstations. I built the Grafana dashboard they can use to track jobs across the pool.
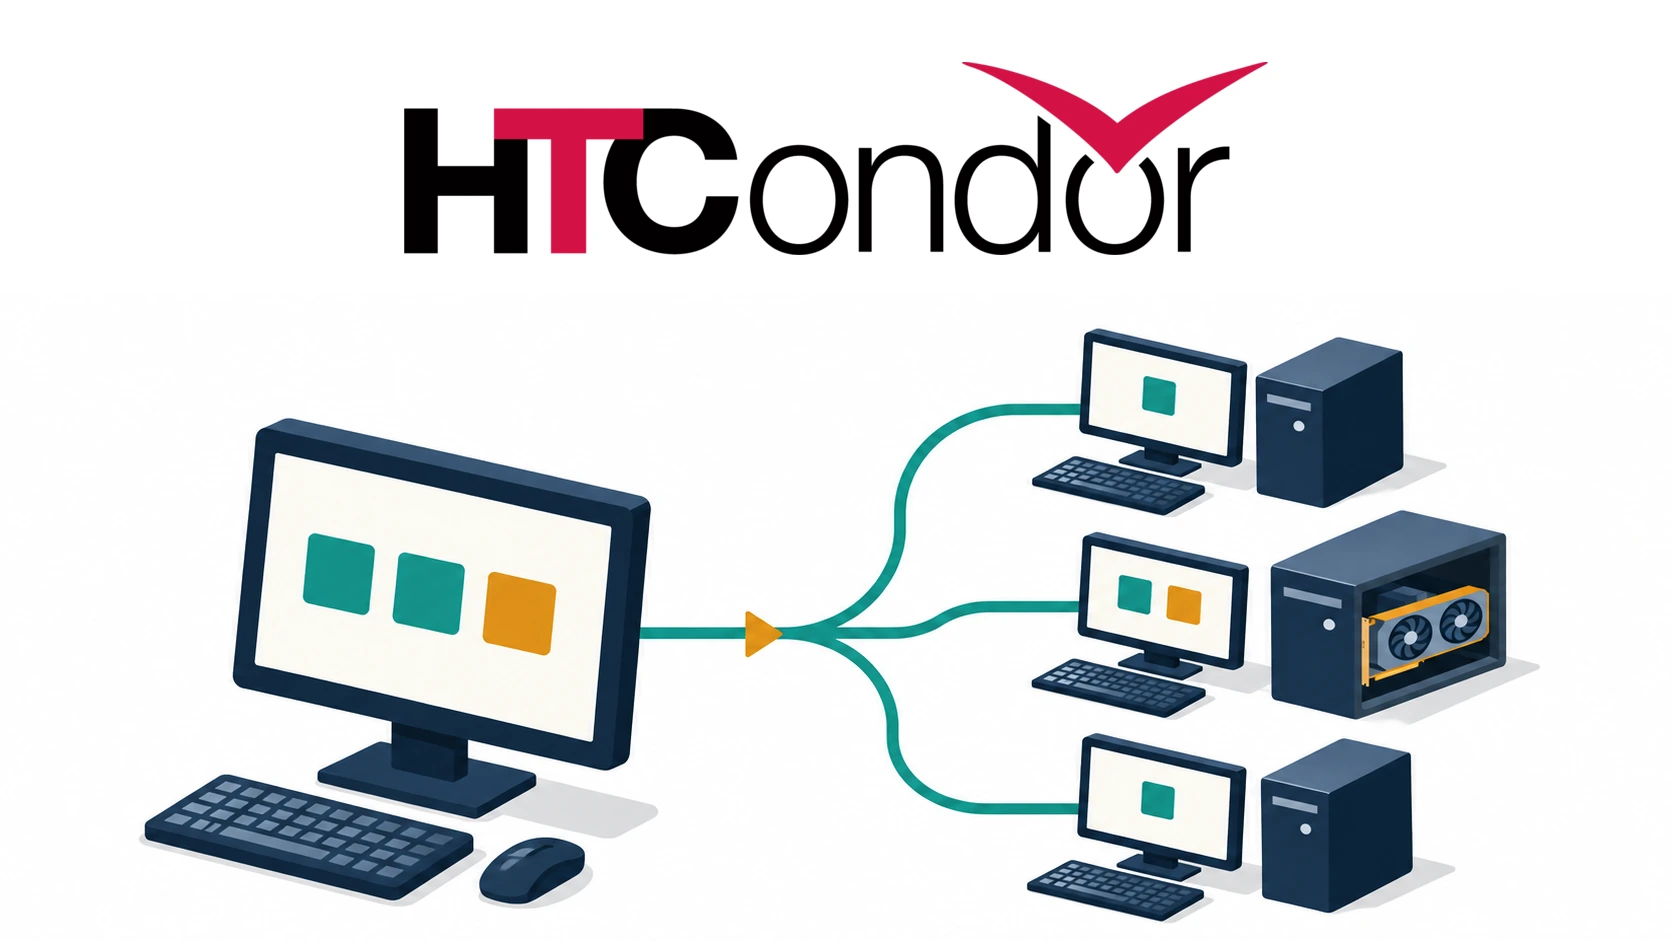
Shared computing for researchers
Our November 2026 inventory listed twelve machines. Researchers can submit a job from their desk, specify the resources it needs, and collect the results on the same machine. I administer the central manager, issue credentials for new workstations, and verify that they can accept jobs. The workstations also serve as desktop computers, so our scheduling policy takes host load into account before starting a new job.
For PyTorch training, we keep Python on shared storage and configure selected NVIDIA workers to let jobs share a physical GPU. For MATLAB analyses, we compile the application on a licensed Linux machine and run it on workers with MATLAB Runtime from our NAS. I documented how researchers can use DAGMan to run a training script with different parameters, limit concurrent submissions, and start a downstream analysis when its inputs are ready.
A dashboard for researchers and operators
I built a Python exporter for HTCondor and a Grafana dashboard that brings job queues, CPU and memory allocations, and per-GPU memory readings into one view. Prometheus collects the scheduler data alongside measurements from the workstations. Researchers can see where a job landed, while I can check how much capacity a worker is offering and how busy the host is.
The lab’s Slack monitor reports when an expected worker disappears from the pool or a GPU collector stops updating. Each alert names the machine and the failed check so the operator knows where to start.
Technical publications
I published six guides covering the pool’s setup, research workflows, and day-to-day operation.
- Building the Ubuntu pool and running a first remote job
- Running PyTorch on shared GPUs
- Deploying compiled MATLAB applications with MATLAB Runtime
- Managing job dependencies and concurrency with DAGMan
- Monitoring jobs and GPU memory with Prometheus and Grafana
- Reporting missing workers and stale GPU metrics to Slack
Tools & Technologies
HTCondor · DAGMan · PyTorch · MATLAB · Python · Prometheus · Grafana · Slack